News from the IT community on November 6th: The MNN team under Taobao has released the MNN-Pocket-0.3B model today, which is designed to meet the task requirements and resource budgets of mobile applications. It takes into account task performance, response speed, and continuous operation experience under limited computing power, memory, and energy consumption.
Focusing on comprehensive mobile applications such as Taobao, the team has implemented the "native large model for mobile applications" into four-dimensional design goals:
- In terms of speed, under specified device and context configurations, the decoding throughput exceeds 200 token per second. This goal is based on the generation throughput of high-speed cloud model services, with the aim of providing a smooth generation experience locally.
- On memory, under specified test conditions, the peak memory usage is below 300MB. Even if a phone has 8 to 16GB of memory, it still needs to be shared among multiple applications by the system. Taking a budget of about 500MB for model modules as an example, keeping the peak inference usage below 300MB can reserve some capacity for context expansion and integration overhead.
- In terms of power consumption, under typical inference loads (input of 512~1024 token, output of 128 token), the energy consumption per single inference increment should not exceed one ten-thousandth of the reference mobile phone battery capacity, meaning that after 100 inferences, the total energy consumption should not exceed 1% of the battery's total capacity, thus controlling the endurance impact of frequent calls.
- In terms of capabilities, the goal is to achieve the performance of an 8B-level model in specified business scenarios. It takes into account both Chinese and English comprehension, world knowledge, mathematical skills, and code reasoning abilities. Emphasis is placed on strengthening command adherence, while also reserving room for expansion in handling long contexts and multi-step tasks.
The MNN team designed and trained this lightweight language model from scratch, which has approximately 300 million parameters and primarily supports both Chinese and English. They integrated the model structure, vocabulary, training data, pre-training and post-training methods, as well as the quantization and inference engines for collaborative optimization, providing a model foundation for Taobao's business and open-source community developers that possesses task understanding capabilities, is responsive, and is easy to adapt to and integrate with.
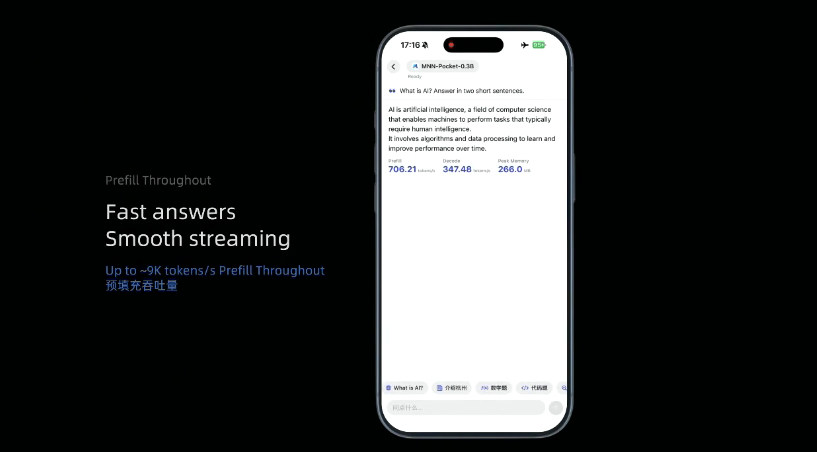
In actual performance tests on the iPhone 18 Pro of Apple, the model ran completely offline through the MNN inference engine, with an average decoding speed of approximately 350 token /s.
The INT4 MNN deployment file of MNN-Pocket-0.3B has a size of only 173MB, containing the model weights, tokenizer, computation graph, and inference configuration.
Under the backend configurations of iPad, Pro M5, Metal, and 512 token test settings, the peak memory usage during model loading and inference Metal increased by 228MB compared to the baseline before loading.
In the same test, the deployment file size of Qwen3-0.6B was 340MB, with a peak memory increase of 427MB. In contrast, the deployment file size of MNN-Pocket-0.3B was reduced by about 49%, and the peak memory increase was reduced by about 47%.
For native large models in mobile applications, a smaller deployment size can reduce the costs of model downloading and updating, while lower operating memory requirements allow for more space to be reserved for business modules such as pages, images, and videos, thereby reducing the resource burden on application integration.
The team evaluated the inference throughput on Apple devices and Android devices, using Metal, OpenCL, and CPU backends. The tests were conducted using MNN version 3.6.2 and INT4 quantization settings with unified running configurations. Each configuration was preheated once and measured five times, and the median throughput was taken. Prefill and Decode were measured separately.
Under the test configurations of iPad Pro M5 / Metal, 512 token, the throughput of MNN-Pocket-0.3B's Prefill reached 8,721 token per second, while the throughput of Decode reached 466 token per second, which is approximately 1.63 times that of Qwen3-0.6B (286 token per second) under the same conditions. On the Snapdragon backend with 8 Gen 5, the throughput of Decode reached 251 token per second.
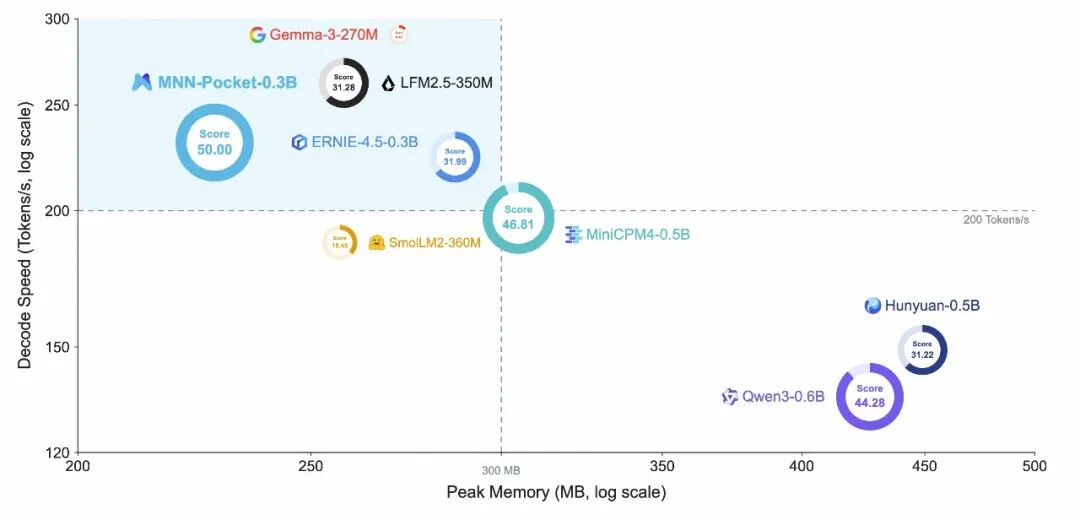
For mobile application native large models, the team set the goal of having a peak memory usage of less than 300MB and a decoding throughput of over 200 token /s as the architectural selection criteria, aiming to retain as much model capacity as possible within the resource budget. Around this goal, the team constructed dense (Dense) model configurations with parameter sizes ranging from about 50M to 1.3B, and tested them under unified inference settings (iPad) Pro M5. Approximately 300M is the largest candidate scale that simultaneously meets both constraints in this set of experiments.
After determining the scale, the team further adjusted the model depth, hidden layer width, and feedforward network with attention configuration within a similar parameter budget. Increasing the number of layers from 16 to 28 led to an improvement in performance; however, when increased to 36 layers, there was no further improvement in evaluation scores, while the decoding throughput decreased from 355 token /s to 323 token /s. The throughput mentioned here is for the purpose of architectural comparison and differs from the test configuration of the final deployed version mentioned earlier.
In the end, MNN-Pocket-0.3B adopts a 28-layer structure and combines it with configurations such as grouped attention queries (GQA) to achieve a balance between model capability, running memory, and inference efficiency.
For Chinese internet mobile applications, MNN-Pocket-0.3B focuses on supporting Chinese and English languages, giving lower priority to the efficiency of processing other languages. Based on the Qwen3 tokenizer, the team has streamlined the vocabulary list from about 151K to 64K, reducing the number of entries by approximately 57%. This reduction in the vocabulary size decreases the parameters and storage requirements for word embedding and the output layer, as well as lowers the output projection overhead during the generation process for each token.
In terms of energy consumption, the team also conducted power consumption tests on the OnePlus 13 (Snapdragon 8 Elite version) using a model that compares MNN with MNN-Pocket-0.3B and bit. Under a CPU4 thread setting, with an input of 1024 and an output of 128 as the baseline load, by collecting battery current and voltage and deducting the idle baseline power consumption, the average incremental energy consumption over three rounds of testing was approximately 2.7J per round. Calculated based on the phone's battery capacity of 6000mAh, performing 100 times such a load task would result in an accumulated incremental energy consumption of about 0.3% of the total battery capacity.
In terms of model capabilities, under the evaluation settings used in the technical report, the English IFEval of MNN-Pocket-0.3B scored 73.20, while the Chinese instructions constructed by the team, following IFEval-zh, scored 74.59, achieving the highest scores among all the compared models.
In the 11 evaluations covering knowledge in both Chinese and English, reasoning, mathematics, code, and instruction following, the model achieved an average score of 50.00, which is higher than that of models of the same scale listed in the report, as well as larger-scale comparison models such as MiniCPM4-0.5B and Qwen3-0.6B. Among them, the model for Chinese mathematics, MGSM-zh, scored 51.20, and the model for code generation, HumanEval, scored 53.66.
The value of native large models for mobile applications still needs to be verified through task adaptation and application integration. For this reason, MNN-Pocket-0.3B provides multiple versions ranging from pre-training, post-training to end-side deployment, allowing researchers and developers to choose a suitable starting point to continue training, evaluating, and building applications.
From research to deployment, the MNN team opens-source model entry points at different stages:
IT's home comes with the following open-source address:
https :// github.com / alibaba / mnn