News from the IT community on October 9th: Liquid AI published a blog post on October 7th, announcing the launch of two open-weight decision-making models in the d1 series: d1-3B supports text and image judgment with 3.12 billion parameters, and d1-omni-600M supports text, image, and voice input with 587 million parameters.
IT Home援引博文介绍, 在 Jev 模型于9月推出并迅速走红后, OpenAI 等公司也相继推出类似的决策模型, Liquid AI 则是加入这一竞争的新成员。本次推出的 d1-3B 和 d1-omni-600M 已在 Hugging Face 公开, 用户可下载、微调并部署。
d1-3B has 3.12 billion parameters and is trained based on the LFM2.5-VL-3B visual language model, supporting both text and image inputs. This model achieved a score of 48.57 on the Decision Index v0.2.1 public test set, and Liquid AI claims that it leads all models with less than 10 billion parameters.
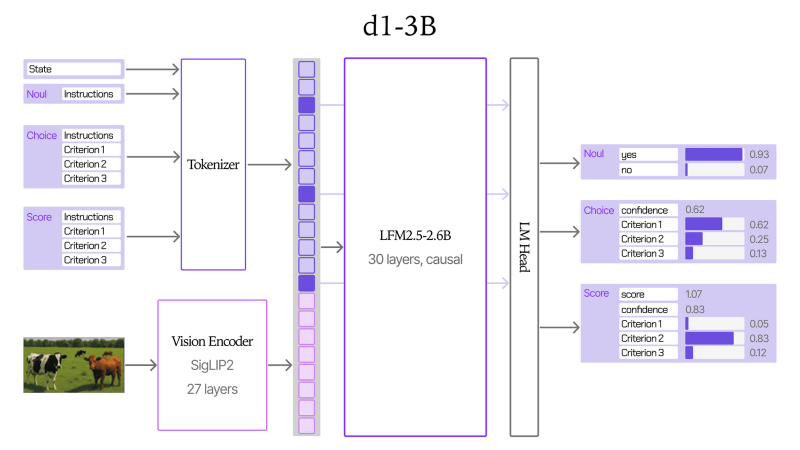
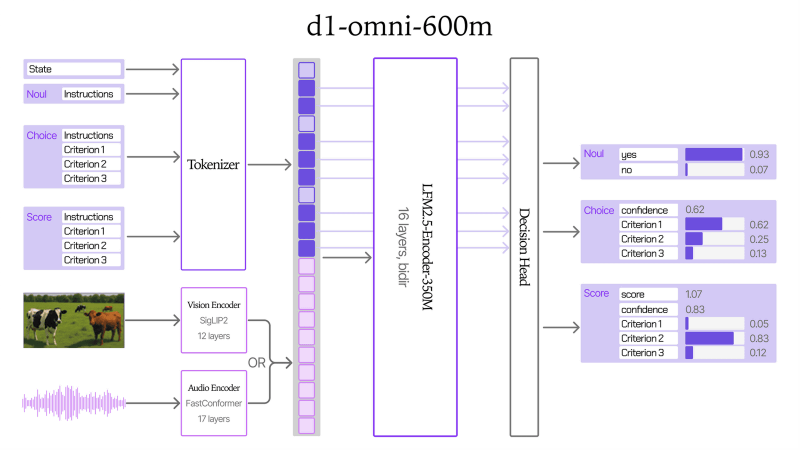
d1-omni-600M has 587 million parameters and is trained using a bidirectional encoder LFM2.5-Encoder-350M. This model supports combined inputs of text and images, or text and speech, and represents the first experimental multimodal decision-making model checkpoint of Liquid AI.
In terms of reasoning speed, d1-3B takes 8 milliseconds to answer a single question on NVIDIA RTX 4090 and 102 milliseconds to process a 384-pixel image. On Jetson AGX Thor, it takes 16 milliseconds for a single question; on Jetson Orin Nano, it takes 50 milliseconds.
tests show that on a GeForce RTX 3060 with 12GB of video memory, the d1-3B model takes 25 milliseconds per judgment, and it takes 146 milliseconds to process a 640×480 pixel image. The peak video memory usage is about 6GB. Another user reported that on a RTX 3090, this model takes 8 milliseconds per judgment.